Scans to text, with the layout kept
Send a scanned PDF or a picture of a page. You get back the text in reading order, with tables split into rows and cells and checkboxes marked as ticked or empty.
Example
Part of a form from a Slovenian public tender, scanned:
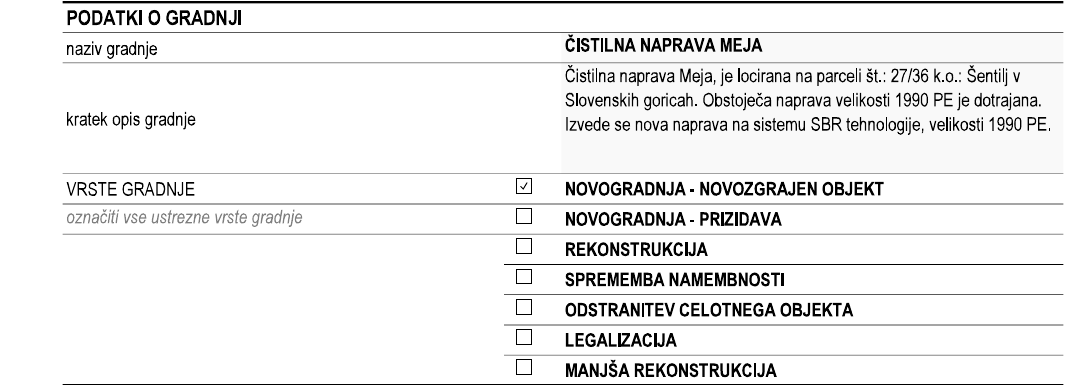
What the service returns for it, as table rows (cells separated by a tab):
PODATKI O GRADNJI
naziv gradnje                        ČISTILNA NAPRAVA MEJA
kratek opis gradnje                  Čistilna naprava Meja, je locirana na parceli št.: 27/36 …
VRSTE GRADNJE                        ☑ NOVOGRADNJA - NOVOZGRAJEN OBJEKT
označiti vse ustrezne vrste gradnje  ☐ NOVOGRADNJA - PRIZIDAVA
                                     ☐ REKONSTRUKCIJA
                                     ☐ SPREMEMBA NAMEMBNOSTI
                                     ☐ ODSTRANITEV CELOTNEGA OBJEKTA
                                     ☐ LEGALIZACIJA
                                     ☐ MANJŠA REKONSTRUKCIJA
Plans and technical drawings are recognised: such a page is marked drawing and its labels are left out of the document text.
The model is Unlimited-OCR-2 (Baidu, MIT licence), 8-bit, reading one page at a time at 300 dpi. It runs on our own server in Slovenia; documents are not stored after the answer.
API
Read a PDF
curl -X POST https://ocr.mediaatlas.si/v1/ocr?pages=1-5 \
  -H "Authorization: Bearer $KEY" \
  -H "Content-Type: application/pdf" \
  --data-binary @document.pdf
Plain text only
curl -X POST "https://ocr.mediaatlas.si/v1/ocr?format=text" \
  -H "Authorization: Bearer $KEY" -H "Content-Type: image/png" --data-binary @page.png
JSON body
POST /v1/ocr
Content-Type: application/json

{"file": "<base64 PDF or image>", "pages": "2-7"}
POST /v1/ocr- The body is a PDF (
application/pdf), one page image (PNG, JPEG, WebP, HEIC from iPhones, TIFF, BMP) or the JSON above. Up to 60 MB and 50 pages per request; ask for longer documents in ranges. - Photos
- Phone photos are turned upright by their orientation tag and straightened when the text is tilted, so a receipt photographed at an angle still keeps its prices and total. Each page says by how many degrees it was turned (
straightened). ?pages=3·?pages=2-7- Pages to read, 1-based and inclusive. A range past the end is cut to the document.
?format=text- Only the document text (
text/plain) instead of JSON. ?multi=1- Read the pages together in one pass (eight at a time) instead of page by page. On our tests the text was the same and it was slower, so it is off by default.
GET /health- Is the model up. No key needed.
Output
{
  "model": "unlimited-ocr-2",
  "page_count": 6,
  "pages": [
    {"page": 1, "text": "REPUBLIKA SLOVENIJA\nUPRAVNA ENOTA MARIBOR\n…",
     "blocks": [
       {"type": "title", "level": 1, "box": [120, 78, 430, 99], "text": "NASLOVNA STRAN NAČRTA"},
       {"type": "table", "box": [117, 164, 928, 819], "html": "<table>…",
        "rows": [["naziv gradnje", "ČISTILNA NAPRAVA MEJA"], ["VRSTE GRADNJE", "☑ NOVOGRADNJA"]]}
     ],
     "drawing": false, "truncated": false, "tokens": 1547, "seconds": 9.4}
  ],
  "text": "…all pages that are not drawings…",
  "ms": 21758
}
blocks- In reading order:
title(withlevel),header,footer,text,table,image,image_caption,ref_text,page_number,other.boxis the position on a 0–1000 grid of the page. drawing- Images cover 30 % of the page or more: a plan or detail rather than a document page. Its text is not in the document
text. truncated- The page hit the output limit, usually an empty form with many blank rows. Blank rows are removed from the answer.
Errors
Always JSON: {"error": {"code": "…", "message": "…"}}. 401 unauthorized (no or wrong key), 400 bad_pages / too_many_pages / bad_json, 413 too_large, 415 unsupported, 422 unreadable_pdf, 502 engine_error.